08. Protein Folding
Archived No proven speedupQAOA on a four-variable toy QUBO with no protein model and no proven speedup. AlphaFold dominates classically. Archived per Troyer framework.
Run Visualisation
Rendered from the committed estimate and simulator artifacts by the viz pipeline.
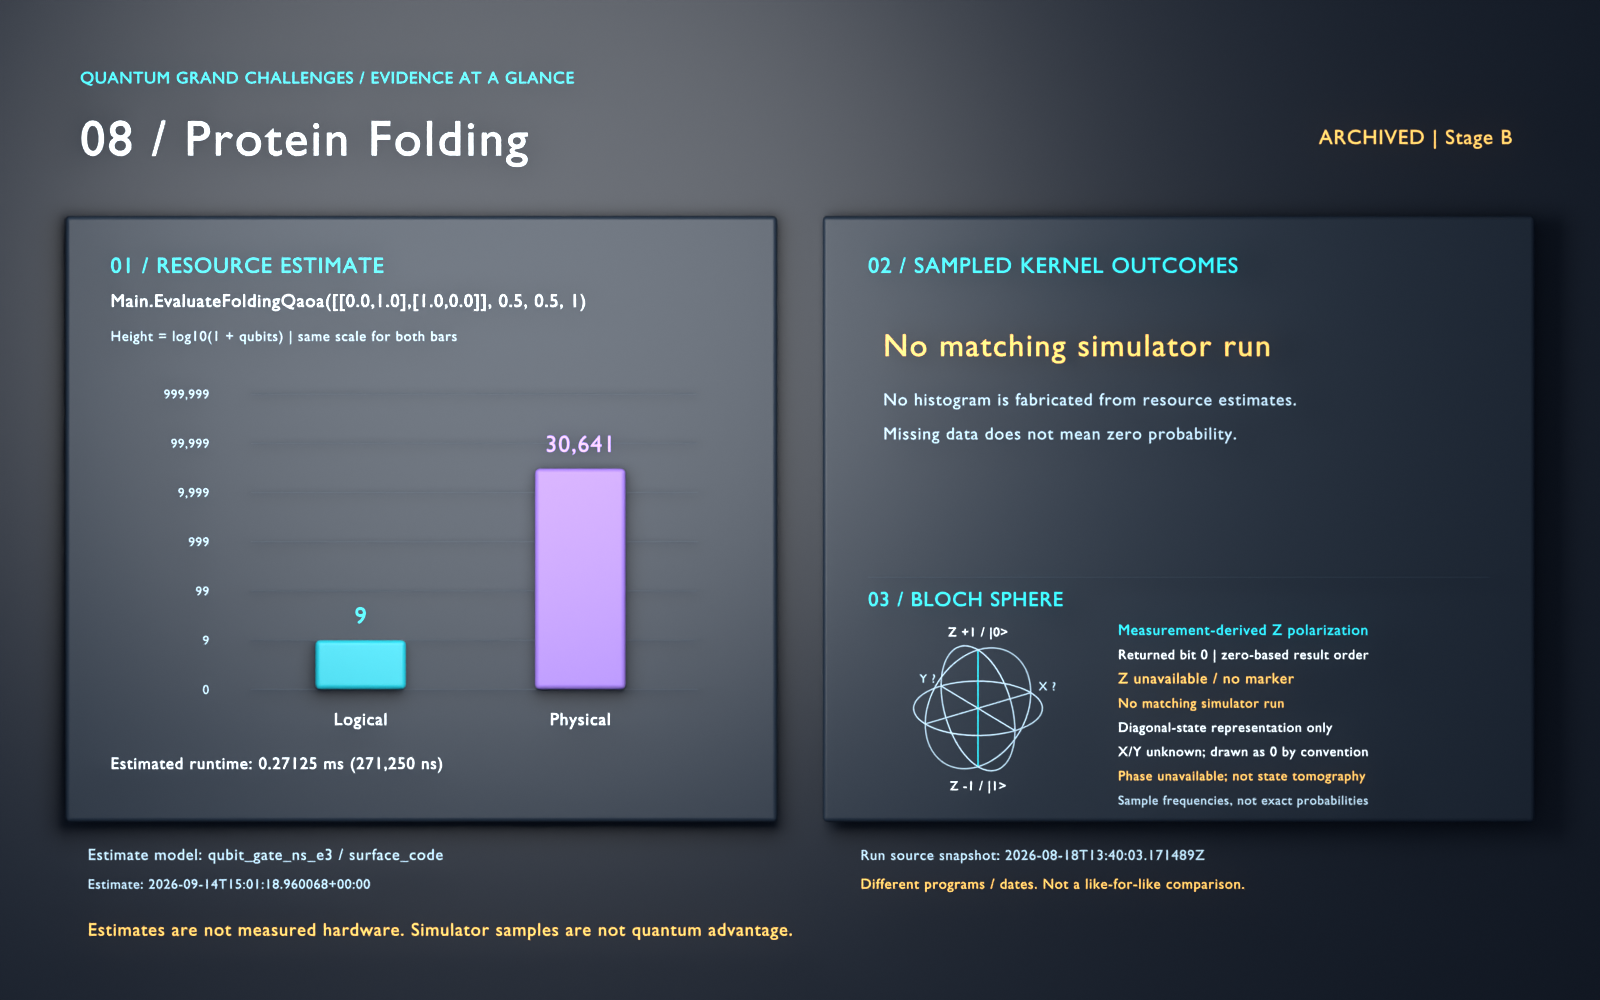
- Resource estimates and sampled kernel outcomes describe different programs. Neither demonstrates quantum advantage; this is not a quantum-state animation.
- No successful local-simulator histogram in the selected run source.
- Archived problem; not an active quantum-advantage candidate.
- This poster was rendered from an earlier estimate (9 logical, 30,641 physical qubits for Main.EvaluateFoldingQaoa([[0.0,1.0],[1.0,0.0]], 0.5, 0.5, 1)). The kernel or the estimated program changed on 2026-09-26; the current estimate is 15 logical, 60,935 physical qubits for Main.EvaluateFoldingQaoa([[0.0,-1.2,-0.3,0.0],[-1.2,0.0,-0.8,-0.5],[-0.3,-0.8,0.0,-1.0],[0.0,-0.5,-1.0,0.0]], 0.47123889803846897, 1.119192382841364, 1).
Resource Estimation (Azure Quantum RE)
Resource Breakdown
Calibration Evidence (20-Run Ensemble)
Noise Resilience (Depolarizing Simulation)
Ideal outcome: [Zero, Zero, Zero, Zero] (32% probability)
Cross-Platform Emulator Results (100 shots)
This run was recorded in April 2026 against a hardware kernel that differed from the estimated program, aligned on 2026-09-26. The shot distribution below is a real measurement, but it is a measurement of a program that no longer exists in this repository, and it has not been re-run against the current kernel.
Troyer Utility-Scale Classification
Classical protein folding has been revolutionized by AI (AlphaFold). QAOA for lattice protein models has no proven advantage. The quantum approach would need to handle realistic all-atom models to compete. This kernel is a four-variable toy QUBO with no protein sequence, lattice or self-avoidance constraint.
These two numbers describe different programs
The resource estimate below is for Main.EvaluateFoldingQaoa([[0.0,-1.2,-0.3,0.0],[-1.2,0.0,-0.8,-0.5],[-0.3,-0.8,0.0,-1.0],[0.0,-0.5,-1.0,0.0]], 0.47123889803846897, 1.119192382841364, 1), the algorithm at utility scale. The Azure Quantum runs executed FoldingQaoaKernel(), a small kernel sized to fit today's hardware. Qubit counts and runtimes from the estimate are not measurements of the run, and the run histogram is not a sample of the estimated circuit.
Pareto Frontier: Qubits vs Runtime
The estimator returns 8 viable configurations, not one answer. Every headline figure on this page comes from the leftmost point, which uses the fewest qubits and is therefore also the slowest. Buying 1.8x the qubits cuts runtime to 0.39x.
qubit_gate_ns_e3 with surface_code, error budget 1e-3. Points are Pareto-optimal: no other configuration is better on both axes.
Multi-Model Resource Comparison
Physical qubit requirements across 6 qubit technologies × 2 QEC schemes (inspired by Troyer Architecture Series, Part 3).
| Qubit Model | QEC | Physical Qubits | Logical Qubits |
|---|---|---|---|
| Superconducting (ns, 1e-4) | surface_code | 11,455 | 15 |
| Trapped Ion (μs, 1e-4) | surface_code | 11,455 | 15 |
| Superconducting (ns, 1e-3) | surface_code | 60,935 | 15 |
| Trapped Ion (μs, 1e-3) | surface_code | 60,935 | 15 |
Problem Documentation
Problem 08 · Toy Ising/QUBO Energy Search
Overview
This archived Q# program is not a protein-folding implementation. It runs a depth-1 QAOA circuit for a four-variable toy Ising/QUBO energy with pair weights that are stored in a matrix named contacts. The code has no protein sequence, lattice walk, or contact-map geometry. It also has no self-avoidance constraint. The protein-folding framing in earlier documentation was therefore false.
Correction (2026-09-26): Earlier text described a protein-folding contact model and future quantum Boltzmann sampling. The verified Q# path builds only a toy Ising/QUBO same-side energy. The hardware kernel now uses the same four-variable toy model and optimized p=1 angles as the estimator entry. Existing website emulator notes predate this alignment.
Verified toy model
- Q# source: `qsharp/src/Main.qs`.
- Hardware kernel: `qsharp/HardwareKernel.qs`.
- Cost function: sum `w_ij` when two bits are equal, with weights `-1.2`, `-0.3`, `-0.8`, `-0.5`, and `-1.0` on five pairs.
- QAOA convention: the same-side penalty layer uses `Rz(2 gamma w_ij)`, so `gamma_standard = 2 gamma` for `exp(-i gamma_standard C)`, up to a global phase.
- Exact brute-force optimum of the toy QUBO: `-3.8`.
- Exact state-vector expectation at the optimized p=1 angles `gamma=0.47123889803846897`, `beta=1.119192382841364`: `-3.1250872910581253`.
- Approximation ratio for this minimization toy objective: `0.8224` relative to the optimum energy magnitude.
- There is no proven QAOA speedup claimed for this problem.
Classical baseline
python/classical_baseline.py is a heuristic knowledge-based scoring script over YAML sequence/contact records. It is useful as a reproducible data-analysis scaffold, but it is not the same objective as the Q# toy QUBO and is not a standard protein-folding solver.
Directory Layout
08_protein_folding/
├── ARCHIVED.md
├── README.md
├── estimates/
├── instances/
├── plots/
├── python/
│   ├── analyze.py
│   ├── classical_baseline.py
│   └── test_baseline.py
└── qsharp/
    ├── HardwareKernel.qs
    ├── qsharp.json
    └── src/
        └── Main.qs
Quick Start
cd problems\archived\08_protein_folding
python python\classical_baseline.py
python python\analyze.py
python -c "from qdk import qsharp; qsharp.init(project_root='qsharp'); print(qsharp.run('Main.RunProteinFolding()', 1))"
Objective Maturity Gate
- **Current gate**: **Stage B complete** for a toy QUBO scaffold only.
- **Next gate target**: none scheduled. Any future protein-folding claim must implement and test an actual protein model before promotion.
DiVincenzo Readiness (Stage C/D Overlay)
| Criterion | Status | Evidence / Notes |
|---|---|---|
| Scalable qubit system | partial | Four toy QUBO variables are implemented; no protein-scale encoding exists. |
| Initialization | partial | Uniform-superposition QAOA initialization is implemented for the toy model. |
| Coherence vs gate time | not-yet | Backend-calibrated coherence-vs-depth evidence is not current after kernel alignment. |
| Universal gate set | partial | The Q# and QASM circuits use standard one- and two-qubit gates. |
| Qubit-specific measurement | partial | Computational-basis measurement is implemented; hardware readout characterization is stale. |
Advantage Claim Contract
- **Claim category (current)**: `theoretical`.
- **Fair baseline**: no fair protein-folding quantum comparison exists in this folder.
- **Residual risks**: the Q# toy objective, classical scoring script, and earlier website emulator records describe different things unless explicitly regenerated from the current kernel.
Reproduce It
cd problems/08_protein_folding
make classical        # Run classical baseline
make analyze          # Generate plots
make build            # Validate Q# compilation
make run              # Run Q# entry point
Key Files
qsharp/src/Main.qsQuantum algorithm implementationqsharp/HardwareKernel.qsAzure-submittable QIR kernelpython/classical_baseline.pyClassical reference implementationestimates/classical_baseline.jsonBaseline metrics